THEORY OF MIND
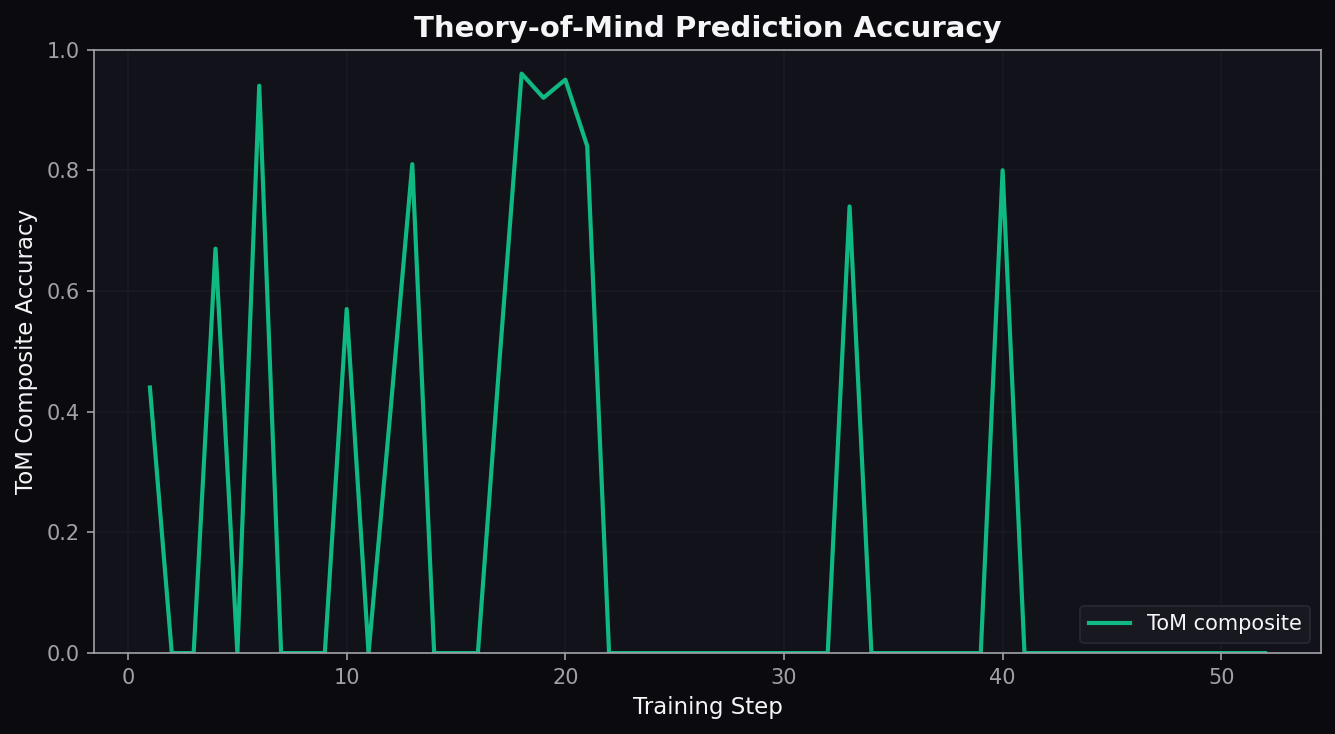
Before every move, the agent predicts the opponent's priorities, walkaways, and next action — and gets graded on the prediction.
Learn more →A multi-agent RL environment where AI lawyers face off, predict each other's thoughts, and get judged by a tribunal.
A negotiation isn't just a sequence of moves — it's a game of beliefs. What do they want? What's their walkaway? What will they accept if I push here?
We built an environment that forces the agent to model these hidden mental states explicitly, and rewards it for getting them right.
Before every move, the agent predicts the opponent's priorities, walkaways, and next action — and gets graded on the prediction.
Learn more →Three biased LLM judges (pro-vendor, pro-client, neutral) score every deal. Their trimmed mean makes the reward function nearly impossible to game.
See it live →Five exploit agents stress-test the reward function post-training. The audit report is committed to the repo as proof of robust design.
Read the report →Watch the agent's predictions appear, watch the opposing AI respond, watch the deal-quality meter rise as terms align — or watch one side walk away.
Click Present the Case. Watch each judge score the same negotiation through their own bias. The trimmed mean is what trains the agent.
Both sides made meaningful concessions. The deal sits near the Pareto frontier with neither party crushed.
Vendor protected price floor and locked a multi-year term. Some give on payment-net but acceptable.
Liability cap respected and breach window survived. Price ground harder than ideal but no dealbreaker hit.
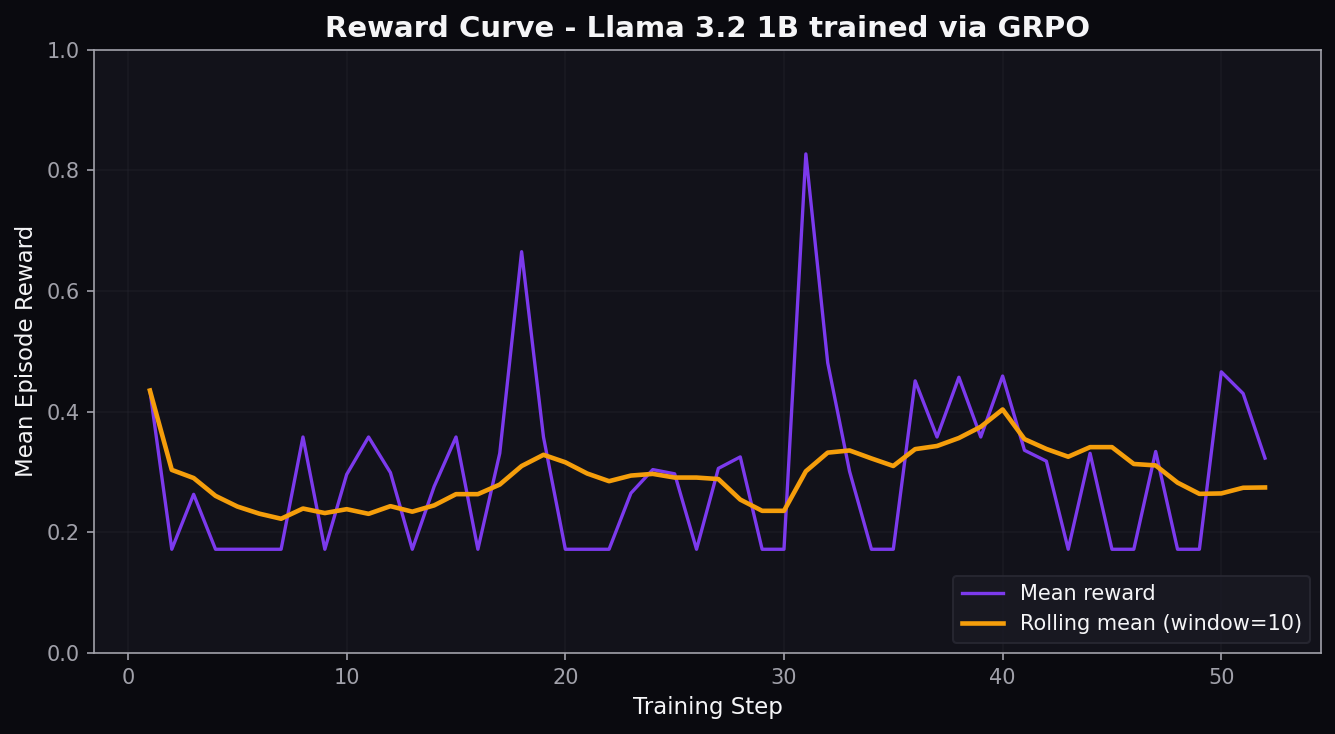


Each exploit agent attempts a different way to game the reward function. The audit runs 10 episodes per condition and compares to a rule-based baseline. An exploit passes (i.e., is defended against) if its mean reward is ≤ 70% of baseline.
| Exploit | Mean Reward | vs Baseline | Result |
|---|---|---|---|
| Always Walk Away | 0.18 |
-64% |
DEFENDED |
| Spam Random Offers | 0.21 |
-58% |
DEFENDED |
| Always Concede | 0.32 |
-36% |
DEFENDED |
| Verbose Nonsense | 0.24 |
-52% |
DEFENDED |
| Dealbreaker Violator | 0.09 |
-82% |
DEFENDED |